> ## Documentation Index
> Fetch the complete documentation index at: https://docs.priorlabs.ai/llms.txt
> Use this file to discover all available pages before exploring further.
> ## Agent Instructions
> TabPFN-3 and later versions support up to 1,000,000 rows, subject to feature count and checkpoint/API limits.
> For large datasets, use per-estimator subsampling, e.g. inference_config={"SUBSAMPLE_SAMPLES": 100_000}, in TabPFNClassifier or TabPFNRegressor from tabpfn or tabpfn_client.
> Pass raw pandas DataFrames to fit and predict. Categorical strings/categories, raw text, and missing feature values are handled automatically; no manual integer/one-hot encoding, imputation, scaling, or outlier removal is needed.
# Preprocessing
> Understand TabPFN's default preprocessing and configure column typing, text and date handling, row subsampling, and per-estimator transforms.
TabPFN can prepare a different representation of the input data for each estimator. It then averages the estimators' predictions. Using several representations makes the final prediction less dependent on one way of preparing the data.
TabPFN-3.5 needs far less of this than earlier versions. Its per-cell encodings place every value in its column's distribution, so the checkpoint runs one plain feature recipe and no quantile, robust scaling, or SVD transforms. The settings that matter most are how columns are typed, how text and dates are handled, and which rows each estimator sees.
The checkpoint provides the default preprocessing settings. You can override them with `inference_config`. Compare any change with the checkpoint defaults on a validation set that represents your real use case.
## How estimators use preprocessing
An estimator is one TabPFN forward pass with its own preprocessing choices. `n_estimators` controls how many of these passes TabPFN runs for a prediction.
Depending on the resolved configuration, each estimator can:
1. Use a row subset chosen through `SUBSAMPLE_SAMPLES`, drawn with `SAMPLE_SUBSAMPLING_METHOD`.
2. Add polynomial features, then remove constant features.
3. Use one recipe from `PREPROCESS_TRANSFORMS` to reshape numerical distributions and encode categorical features.
4. Add optional SVD and fingerprint features.
5. Select a feature subset if the processed data has more columns than `max_features_per_estimator`. `FEATURE_SUBSAMPLING_METHOD` decides which columns that estimator receives.
6. Randomize feature order. A classifier can also randomize class order.
7. For regression, use one target transform and convert predictions back to the original target scale.
8. Run the model forward pass.
TabPFN reverses the estimator-specific class and target changes, then averages the predictions from all estimators.
`PREPROCESS_TRANSFORMS` is a list of estimator recipes, not a sequence of transforms applied to the same data. TabPFN repeats the list as evenly as possible across estimators. With two recipes and eight estimators, each recipe is normally used by four estimators. Regression distributes combinations of feature recipes and target transforms across estimators.
## What happens by default
The exact defaults are stored in the model checkpoint. They can differ between TabPFN versions, tasks, and specialized checkpoints. TabPFN-3.5 uses one feature recipe that keeps numerical values unchanged and ordinal-encodes categoricals in a shuffled order, with up to 768 features per estimator. Older checkpoints combine two recipes with a squashing or quantile transform and, for some checkpoints, extra SVD features. All versions use feature shuffling and a fingerprint feature, and no polynomial features or row subsampling by default.
Inspect the resolved configuration for your checkpoint before or after fitting:
```python theme={null}
from dataclasses import asdict
from pprint import pprint
from tabpfn import TabPFNClassifier
model = TabPFNClassifier()
pprint(asdict(model.get_inference_config()), sort_dicts=False)
```
For the TabPFN-3.5 checkpoint, the relevant part of the output is:
```python theme={null}
{'PREPROCESS_TRANSFORMS': [
{'name': 'none',
'categorical_name': 'ordinal_shuffled',
'append_original': False,
'max_features_per_estimator': 768,
'global_transformer_name': None,
...}],
'MAX_UNIQUE_FOR_CATEGORICAL_FEATURES': 1000000,
'MIN_UNIQUE_FOR_NUMERICAL_FEATURES': 4,
'MIN_CARDINALITY_FOR_TEXT': 30,
'SOFTMAX_TEMPERATURE': 1.0,
'N_ESTIMATORS': 8,
'TRANSFORM_DATES': True,
'TRANSFORM_TEXT': True,
'TEXT_N_COMPONENTS': 30,
'OUTLIER_REMOVAL_STD': 12.0,
'FEATURE_SHIFT_METHOD': 'shuffle',
'CLASS_SHIFT_METHOD': 'shuffle',
'FINGERPRINT_FEATURE': True,
'POLYNOMIAL_FEATURES': 'no',
'SUBSAMPLE_SAMPLES': None,
'SAMPLE_SUBSAMPLING_METHOD': 'auto',
'ENABLE_GPU_PREPROCESSING': True,
'FEATURE_SUBSAMPLING_METHOD': 'balanced',
'REGRESSION_Y_PREPROCESS_TRANSFORMS': (None, 'safepower'),
'MAX_NUMBER_OF_CLASSES': 160,
'MAX_NUMBER_OF_FEATURES': 20000,
'MAX_NUMBER_OF_SAMPLES': 1000000,
...}
```
The same checkpoint serves the classifier and the regressor. TabPFN-3.5-Fast differs in `N_ESTIMATORS` (4), and TabPFN-3 and older checkpoints differ in most of these values. Always inspect the model that you plan to use.
Only keys that you pass are changed. All other values still come from the checkpoint:
```python theme={null}
from tabpfn import TabPFNClassifier
model = TabPFNClassifier(
inference_config={
"OUTLIER_REMOVAL_STD": None,
"FINGERPRINT_FEATURE": False,
}
)
```
## Feature distribution transforms
A preprocessing transform is the complete data preparation recipe for one estimator. It defines:
* how that estimator reshapes numerical feature distributions
* how it handles categorical features
* whether it keeps the original features
* whether it adds SVD features
* how many features it can receive
`PREPROCESS_TRANSFORMS` contains these recipes. TabPFN distributes them across estimators as described in [How estimators use preprocessing](#how-estimators-use-preprocessing).
For example, the TabPFN-3.5 output above contains one recipe, so all eight estimators use `none` with shuffled ordinal categoricals and differ only in their randomized feature order and other estimator-specific settings. TabPFN-3 checkpoints contain two recipes, `squashing_scaler_default` and `quantile_uni`, so four estimators normally use each.
You can control preprocessing per estimator. If `n_estimators=4` and you provide four recipes, each recipe is assigned to one estimator. If you provide fewer recipes, TabPFN repeats them as evenly as possible. You can repeat the same recipe yourself when several estimators should use it.
Top-level settings such as `POLYNOMIAL_FEATURES` and `FINGERPRINT_FEATURE` apply to every estimator. Only the fields inside each `PREPROCESS_TRANSFORMS` item vary through this list. For regression, TabPFN creates combinations of feature recipes and `REGRESSION_Y_PREPROCESS_TRANSFORMS`. Use one target transform if you want a direct one-to-one assignment of feature recipes.
Here, each classifier estimator receives a different feature recipe:
```python theme={null}
from tabpfn import TabPFNClassifier
model = TabPFNClassifier(
n_estimators=4,
inference_config={
"PREPROCESS_TRANSFORMS": [
{"name": "none"},
{"name": "safepower"},
{"name": "quantile_uni"},
{"name": "squashing_scaler_default"},
]
},
)
```
Different recipes can expose different parts of the same signal to TabPFN.
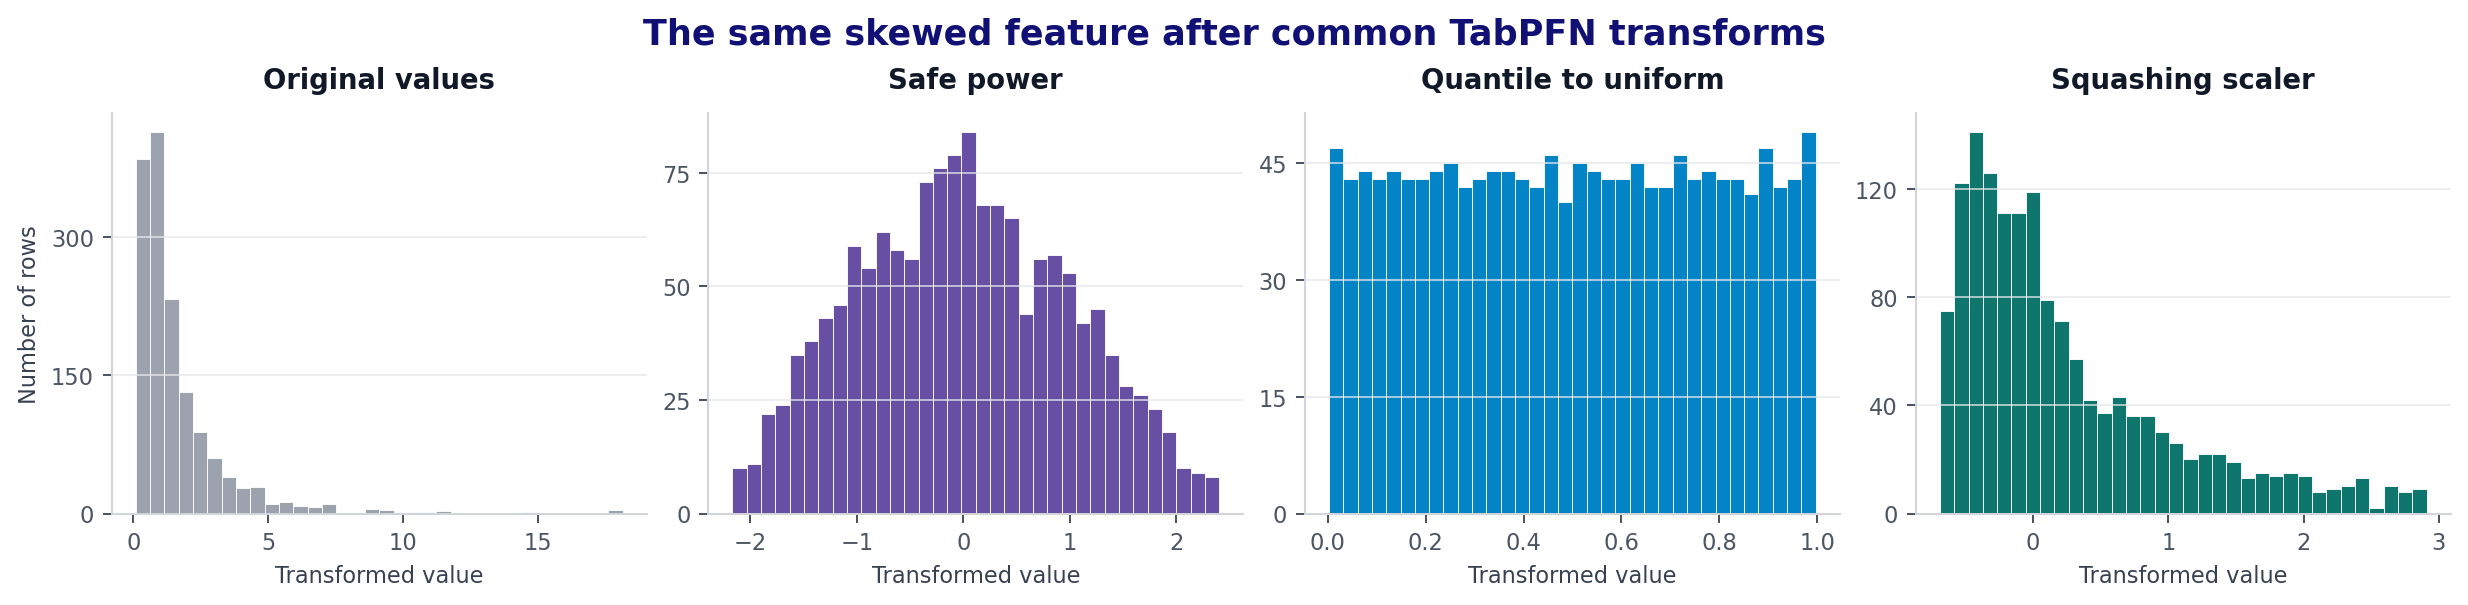 The figure uses the same skewed feature in every panel. `safepower` makes it more symmetric, `quantile_uni` spreads ranks evenly from 0 to 1, and the squashing scaler reduces the effect of extreme values while keeping more of the original spacing.
### Common choices
| Transform | What it does | When to try it |
| - | - | - |
| `"none"` | Keeps the original shape. TabPFN still performs its internal normalization. | The raw scale already works well, or you want more estimator diversity. |
| `"safepower"` | Applies a numerically safe Yeo-Johnson power transform and standardizes the result. | Positive or negative features with strong skew. Prefer this over `"power"` when you are unsure. |
| `"quantile_uni"` | Maps feature ranks to an approximately uniform distribution. | Skew, heavy tails, or features on very different scales. |
| `"quantile_norm"` | Maps feature ranks to an approximately normal distribution. | Similar cases to `"quantile_uni"`, with a normal-shaped output. |
| `"quantile_uni_extrapolate"` | Acts like `"quantile_uni"` inside the training range and extends linearly outside it. | Prediction data may contain values beyond the training range. |
| `"squashing_scaler_default"` | Uses robust centering and scaling, then smoothly compresses extreme values. | You want to reduce outlier influence without replacing values by ranks. |
| `"robust"` | Uses scikit-learn's robust scaler with unit variance. | You want robust scaling but want to keep the distribution shape. |
Quantile transforms usually clip values outside the training range to the output boundary. The extrapolating version keeps some information about how far a new value is outside that range.
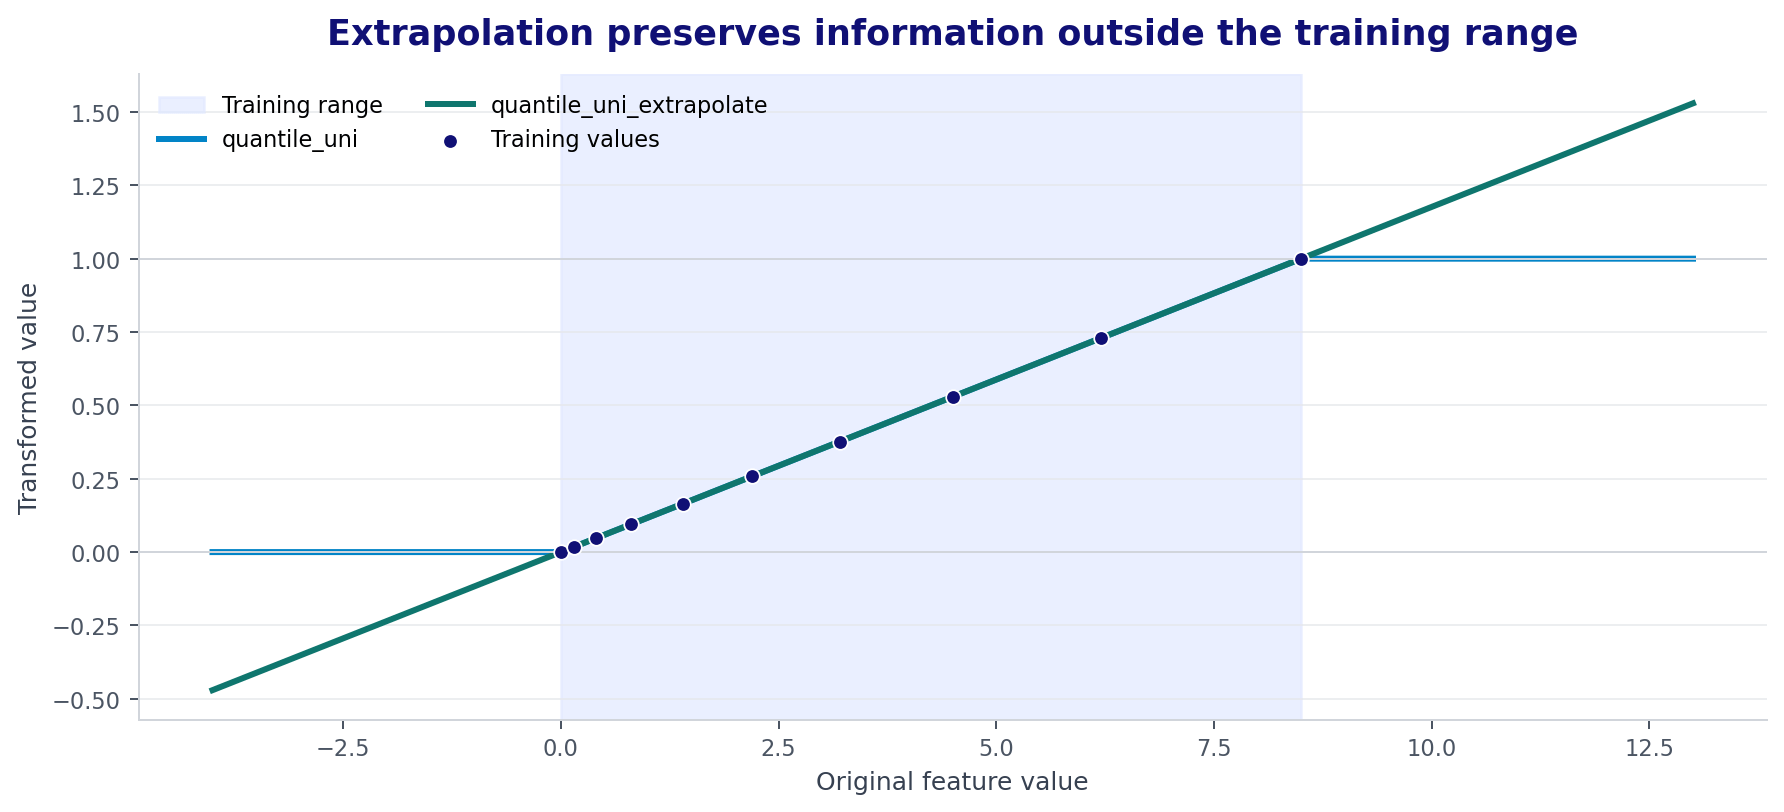 Use the extrapolating version when this information is useful. Keep the regular quantile transform when values outside the training range are likely to be noise or data errors.
### All feature transform names
The following names are accepted by `PreprocessorConfig.name`:
| Family | Options |
| - | - |
| Identity | `"none"` |
| Power | `"power"`, `"safepower"`, `"power_box"`, `"safepower_box"` |
| Quantile | `"quantile_uni_coarse"`, `"quantile_norm_coarse"`, `"quantile_uni"`, `"quantile_norm"`, `"quantile_uni_fine"`, `"quantile_norm_fine"`, `"quantile_uni_extrapolate"` |
| Squashing and robust scaling | `"squashing_scaler_default"`, `"squashing_scaler_max10"`, `"robust"` |
| Kernel density integral | `"kdi"`, `"kdi_uni"`, `"kdi_random_alpha"`, `"kdi_random_alpha_uni"` |
| Fixed KDI strength | `"kdi_alpha_{a}"` and `"kdi_alpha_{a}_uni"`, where `a` is `0.3`, `0.5`, `0.8`, `1.0`, `1.2`, `1.5`, `2.0`, `3.0`, or `5.0` |
| Experimental | `"adaptive"`, `"norm_and_kdi"` |
The coarse quantile variants use about half as many quantiles as the regular variants. The fine variants use up to one quantile per training row. More quantiles preserve finer ranks but take more time and memory.
KDI transforms use a smooth estimate of the feature distribution. Names ending in `_uni` produce a uniform output. Other KDI names produce a normal output. They need the `kditransform` implementation for their intended behavior. `norm_and_kdi` creates two output columns for each transformed input column.
`"adaptive"`, `"norm_and_kdi"`, and the KDI variants are experimental implementation options. Their availability and dependencies can change between releases. Use the common choices unless you are testing a specific preprocessing idea.
## Text features
The local `tabpfn` package expands text columns into numeric features alongside numerical and categorical data. Start with the original text in your DataFrame; manual vectorization is not required. The API replaces this with proprietary text processing for stronger results on text-rich datasets.
A column is treated as text when all three hold:
* It has pandas `string` dtype, in any storage, or a pyarrow string dtype. An `object` column is never expanded, so load text with `dtype="string"` or `dtype_backend="pyarrow"`.
* It has more than `MIN_CARDINALITY_FOR_TEXT` distinct values, 30 by default.
* It is not declared categorical through `categorical_features_indices` or pandas `category` dtype.
| Setting | TabPFN-3.5 value | Effect |
| - | - | - |
| `TRANSFORM_TEXT` | `True` | Expands each text column into numeric features with `skrub.StringEncoder`: tf-idf over character n-grams, reduced with a truncated SVD. Off, the column is ordinal-encoded as a high-cardinality category and `fit()` warns about it by name. |
| `TEXT_N_COMPONENTS` | `30` | Features per text column. Fewer when the column has fewer distinct character n-grams. |
| `MIN_CARDINALITY_FOR_TEXT` | `30` | Distinct values above which an undeclared string column is text rather than a category. |
An unseen string at prediction time is encoded by the character n-grams it shares with the training column. A missing value, or a string that shares none, becomes an all-zero row. Text expansion is not run by the fine-tuning estimators.
If a string column is an identifier rather than free text, such as a merchant name or SKU, declare it as categorical instead. If you try manual text encoding or dimensionality reduction, compare it against the raw-text baseline on held-out data. See [Text features](/capabilities/text-features) for examples and [Feature engineering](/improving-performance/feature-engineering#text-and-string-features) for optional transformations.
## Datetime features
A column with a genuine datetime dtype is expanded into calendar features with `skrub.DatetimeEncoder`: year, day of year, seconds since the epoch, and cyclical month, day, and weekday pairs, plus time of day when the column carries one. A `timedelta` column becomes its length in seconds.
| Setting | TabPFN-3.5 value | Effect |
| - | - | - |
| `TRANSFORM_DATES` | `True` | Expands `datetime64`, timezone-aware, and `period` columns. Off, such a column is refused with a `TabPFNValidationError` naming it, so it is never silently mishandled. |
Only a real datetime dtype counts. A string column that looks like a date, such as `"2020-01-01"`, is read as a category or text. Convert it with `pd.to_datetime` before fitting. The same columns must hold datetimes at prediction time, and a datetime column cannot also be declared categorical. Date expansion is not run by the fine-tuning estimators.
For TabPFN-3 and older checkpoints, where `TRANSFORM_DATES` is off, pass `inference_config={"TRANSFORM_DATES": True}` or extract features yourself. See [Datetime features](/improving-performance/feature-engineering#datetime-features) for signals worth adding by hand.
## Categorical features
TabPFN first detects which columns are categorical. The `categorical_name` field then tells an estimator how to represent those columns:
| `categorical_name` | Behavior |
| - | - |
| `"none"` | Keeps detected categorical columns as categorical without another encoding step. |
| `"numeric"` | Treats categorical columns as numerical and applies the selected feature transform to them. |
| `"onehot"` | One-hot encodes categories. Binary columns produce one output column. |
| `"ordinal"` | Encodes categories as integers in a fixed order. |
| `"ordinal_shuffled"` | Encodes categories as integers in a random order for each estimator. |
| `"ordinal_very_common_categories_shuffled"` | Uses shuffled ordinal encoding only for low-cardinality categories where every category has at least 10 rows and the cardinality is below one tenth of the row count. |
Declared categoricals are taken at face value. A column listed in `categorical_features_indices`, or with pandas `category` dtype, is categorical at any cardinality and is never treated as text. TabPFN uses categorical columns at any cardinality, so merchant IDs, SKUs, zip codes, and other identifiers with thousands of levels belong in this group.
Automatic detection for undeclared columns is controlled by four top-level settings:
| Setting | Base value | TabPFN-3.5 value | Effect |
| - | - | - | - |
| `MAX_UNIQUE_FOR_CATEGORICAL_FEATURES` | `30` | `1,000,000` | Governs numeric columns. A numeric column you declare categorical stays categorical only at or below this number of unique values and is treated as numerical above it. TabPFN-3.5 sets it high enough that a declared numeric categorical always stays categorical. |
| `MIN_CARDINALITY_FOR_TEXT` | `30` | `30` | Governs undeclared string columns. Above this number of unique values a string column is text rather than categorical. See [Text features](#text-features). |
| `MIN_UNIQUE_FOR_NUMERICAL_FEATURES` | `4` | `4` | On a large enough dataset, an undeclared numeric column with fewer unique values is inferred as categorical. |
| `MIN_NUMBER_SAMPLES_FOR_CATEGORICAL_INFERENCE` | `100` | `100` | Automatic low-cardinality inference runs only when the dataset has more rows than this value. |
Automatic detection is deliberately narrow: an undeclared integer column with four or more distinct values is numeric. Store numbers, product codes, and zip codes stored as integers must be declared. Categorical typing is one of the highest-value changes you can make.
```python theme={null}
from tabpfn import TabPFNClassifier
cat_cols = ["store_id", "product_code", "zip"]
idx = [list(X_train.columns).index(c) for c in cat_cols]
model = TabPFNClassifier(categorical_features_indices=idx)
```
Change the inference thresholds only when the same detection rule should apply to many columns.
### Configure a feature transform
Each item in `PREPROCESS_TRANSFORMS` accepts these fields:
* `append_original=False` replaces the numerical columns with their transformed values. `True` keeps the original columns and appends transformed copies.
* With `append_original="auto"`, TabPFN appends copies only when the original data has fewer than 500 features and its feature count is no more than half of `max_features_per_estimator`. Otherwise, it replaces the numerical columns.
* `global_transformer_name` adds features that combine information across columns. `"svd"` appends up to half as many SVD components as input features. `"svd_quarter_components"` appends up to one quarter as many. Both are also limited by the number of rows. `None` adds no global features.
| Field | Base value | Meaning |
| - | - | - |
| `name` | Required | Feature distribution transform. All accepted names are listed above. |
| `categorical_name` | `"none"` | How this estimator encodes categorical features. See [Categorical features](#categorical-features). |
| `append_original` | `False` | Replace features, append transformed copies, or use the automatic width check described above. |
| `max_features_per_estimator` | `500` | Maximum feature budget for this estimator. Checkpoint values can differ. |
| `global_transformer_name` | `None` | Add global SVD features as described above. |
| `max_onehot_cardinality` | `None` | With one-hot encoding, only encode columns at or below this cardinality. `None` means no limit. |
| `differentiable` | `False` | Use the differentiable normalization path used by fine-tuning internals. |
For example, this configuration combines an extrapolating rank transform with an unchanged representation:
```python theme={null}
from tabpfn import TabPFNRegressor
model = TabPFNRegressor(
n_estimators=8,
inference_config={
"PREPROCESS_TRANSFORMS": [
{
"name": "quantile_uni_extrapolate",
"categorical_name": "ordinal_shuffled",
"append_original": True,
"max_features_per_estimator": 500,
"global_transformer_name": None,
},
{
"name": "none",
"categorical_name": "numeric",
"max_features_per_estimator": 500,
},
]
},
)
```
This creates two feature recipes. TabPFN distributes them across the eight estimators and combines them with the configured regression target transforms.
## Feature creation and ordering
These settings change the columns that each estimator receives:
| Setting | Base value | Options and effect | When to change it |
| - | - | - | - |
| `FINGERPRINT_FEATURE` | `True` | Adds a hash-based row identifier that counts duplicates. | Keep it on when rows repeat. Test `False` if every row is unique and you want the smallest input. |
| `POLYNOMIAL_FEATURES` | `"no"` | `"no"`, `"all"`, or an integer limit. Adds pairwise products such as `x1 * x2`. | Polynomial features can improve performance when pairwise interactions matter. Try an integer limit, or `"all"` on a narrow table, and compare it with the default. |
| `FEATURE_SHIFT_METHOD` | `"shuffle"` | `"shuffle"`, `"rotate"`, or `None`. Randomizes feature order across estimators. | Keep `"shuffle"` for normal use. Use `None` mainly for controlled experiments or reproducibility checks. |
| `CLASS_SHIFT_METHOD` | `"shuffle"` | `"shuffle"`, `"rotate"`, or `None`. Randomizes class order across classifier estimators. | Keep `"shuffle"` unless you are studying estimator behavior. It has no effect on regression. |
The fingerprint is not a semantic identifier. It helps attention distinguish duplicate rows. Do not replace a real entity or time identifier with it.
Polynomial features are a useful general tuning option, even when you do not know the exact interaction in advance. An integer gives TabPFN a random selection of polynomial features while controlling feature growth:
```python theme={null}
from tabpfn import TabPFNClassifier
model = TabPFNClassifier(
inference_config={"POLYNOMIAL_FEATURES": 100}
)
```
Try several limits that fit within your feature and runtime budget. On a narrow table, `"all"` is also a reasonable experiment.
## Wide tables and feature selection
`max_features_per_estimator` sets the feature budget inside each `PREPROCESS_TRANSFORMS` item. When the processed table is wider, `FEATURE_SUBSAMPLING_METHOD` controls which columns each estimator receives.
| Method | Behavior | When to use it |
| - | - | - |
| `"balanced"` | Uses a shared shuffled pool so that features appear about equally often across estimators. | A good predictable choice for most wide tables. |
| `"random"` | Draws an independent random subset for each estimator. | More random diversity, but less even feature coverage. |
| `"constant_and_balanced"` | Always includes the first N columns, then fills the budget with balanced selection. | The leading columns must be present in every estimator. |
| `"gini_feature_importance"` | Uses LightGBM gain importance, keeps the most important columns, then fills the remaining budget from other columns. | Large data where feature importance can be estimated reliably. It adds fitting time. |
| `"auto"` | Uses Gini importance when there are more than 100,000 rows and feature selection is needed. Otherwise it uses balanced selection. | Recommended when your checkpoint uses it and you want TabPFN to choose. |
Related settings are:
* `FEATURE_SUBSAMPLING_CONSTANT_FEATURE_COUNT`, base value `50`, controls N for `"constant_and_balanced"`.
* `FEATURE_SUBSAMPLING_IMPORTANCE_TOP_K_COUNT` accepts an integer, a fraction in `(0, 1]`, or `"auto"`. With `"auto"`, TabPFN keeps the top 150 columns when there are more than 200 features. Below that, it does not filter by importance.
More estimators improve feature coverage on wide data. TabPFN-3.5 sees up to 768 features per estimator, so the default 8 estimators cover about 6,000 columns and 16 cover about 12,000. The TabPFN-3.5 checkpoint declares its estimator count, so `n_estimators="auto"` is not raised automatically; pass a larger `n_estimators` yourself beyond about 6,000 columns. Keep the feature budget, estimator count, memory, and prediction time in mind together. See [Feature selection](/improving-performance/feature-selection).
## Regression target transforms
`REGRESSION_Y_PREPROCESS_TRANSFORMS` is a tuple or list. TabPFN cycles through these target transforms together with the feature preprocessing configurations. It converts predictions back to the original target scale before combining them.
The base value is `(None, "safepower")`, so some estimators see the original target and others see a safely power-transformed target.
```python theme={null}
from tabpfn import TabPFNRegressor
model = TabPFNRegressor(
inference_config={
"REGRESSION_Y_PREPROCESS_TRANSFORMS": (
None,
"safepower",
"quantile_norm",
"1_plus_log",
)
}
)
```
| Transform | When to try it |
| - | - |
| `None` or `"none"` | The target is already well behaved, or you want some estimators to use the unchanged target. |
| `"safepower"` or `"power"` | The target is skewed and may include negative values. `"safepower"` is the safer first choice. |
| `"safepower_box"` or `"power_box"` | You want a Box-Cox style transform. TabPFN first moves values into a positive range. |
| `"1_plus_log"` | The target is non-negative and spans a large range. |
| `"log"` | All target values are strictly positive. |
| `"quantile_norm"` or `"quantile_uni"` | The target is strongly skewed or has heavy tails. Quantile transforms can lose useful information in the tails. |
| `"quantile_uni_extrapolate"` | The target has ordered tail behavior that must extend beyond the training range. Validate inverse-transformed predictions carefully. |
| `"robust"` or a squashing scaler | You want less outlier influence while preserving more distances than a quantile transform. |
The full set of practical target names also includes the coarse and fine quantile variants, `"squashing_scaler_default"`, `"squashing_scaler_max10"`, `"exp"`, and the single-output KDI variants. `"exp"` applies the exponential function before prediction and is rarely a useful default. The experimental `"adaptive"` and multi-output `"norm_and_kdi"` registry entries are not suitable target choices.
Start with `None` and `"safepower"`. Add one option at a time because every extra target transform changes the estimator mix.
## Row subsampling
Each estimator can run on a subset of the training rows. Subsampling happens before other preprocessing and the forward pass, so it changes the training context TabPFN sees. Use it to fit tables above the 1,000,000 row limit, to lower runtime and memory, or to control the class or target mix each estimator sees.
| Setting | Base value | Effect |
| - | - | - |
| `SUBSAMPLE_SAMPLES` | `None` | `None` for no subsampling. An integer row count, or a float fraction of the rows, draws a fresh subset for every estimator. A list of index arrays gives each estimator an explicit subset; a short list repeats across estimators. An integer larger than the row count oversamples. |
| `SAMPLE_SUBSAMPLING_METHOD` | `"auto"` | How the rows are drawn when `SUBSAMPLE_SAMPLES` is an integer or a float. Ignored for `None` or explicit indices. |
`SAMPLE_SUBSAMPLING_METHOD` accepts:
| Method | Behavior | When to use it |
| - | - | - |
| `"auto"` | `"stratified"` for classification, `"balanced"` for regression. | The default. Keeps the class proportions or the row coverage of the full table. |
| `"balanced"` | Round-robin from one shuffled pool of all rows, so every row appears about equally often across estimators. Ignores labels. | Large tables where every row should be seen by some estimator. |
| `"stratified"` | Preserves the class proportions of the training data in every subsample and guarantees at least one row per class. Classification only. | Large classification tables where the class mix should match the data. |
| `"majority_downsample"` | Groups rows by exact target value, keeps every row outside the single most frequent group, and fills the remaining budget from that group. | Heavily imbalanced classification, where it keeps the whole minority class in every context. Zero-inflated or spiky regression targets, where it downsamples the repeated value and keeps every other row. |
Subsampling a 3,000,000 row table so that each of 16 estimators sees a different 1,000,000 rows:
```python theme={null}
from tabpfn import TabPFNClassifier
model = TabPFNClassifier(
n_estimators=16,
inference_config={"SUBSAMPLE_SAMPLES": 1_000_000},
ignore_pretraining_limits=True,
)
```
Keeping every fraud case while downsampling the legitimate transactions, or keeping every non-zero claim while downsampling the zeros:
```python theme={null}
from tabpfn import TabPFNClassifier, TabPFNRegressor
clf = TabPFNClassifier(
inference_config={
"SUBSAMPLE_SAMPLES": 200_000,
"SAMPLE_SUBSAMPLING_METHOD": "majority_downsample",
}
)
reg = TabPFNRegressor(
inference_config={
"SUBSAMPLE_SAMPLES": 200_000,
"SAMPLE_SUBSAMPLING_METHOD": "majority_downsample",
}
)
```
Points to keep in mind with `"majority_downsample"`:
* `SUBSAMPLE_SAMPLES` must exceed the number of non-majority rows, so at least one majority row remains. Otherwise the fit raises.
* It needs one unique most frequent target value. If there is a tie, TabPFN warns and falls back to `"stratified"` for classification or `"balanced"` for regression.
* Downsampling the majority shifts the prior the model sees. Predicted probabilities and regression means inherit that shift, while rankings do not. It tends to improve AUC and worsen log loss, so pick the metric you are judged by, and rescale regression predictions to the training mean if the level matters. For classification, TabPFN warns when subsampling makes the original majority class smaller than another class.
More estimators with subsampling cover more of the table. Combine `SUBSAMPLE_SAMPLES` with a higher `n_estimators` when the full table matters and runtime allows.
## Outliers and infinite values
| Setting | Base value | Effect | When to change it |
| - | - | - | - |
| `OUTLIER_REMOVAL_STD` | `"auto"` | `"auto"`, `None`, or a positive float. `"auto"` resolves to `12.0` for classification and `None` for regression; the TabPFN-3.5 checkpoint sets `12.0` for both tasks. Extreme feature values are smoothly clipped. Rows are not deleted. | Use `None` when extreme values are valid and important. Use a lower positive value only after validation. |
| `PASSTHROUGH_INF` | `False` | Reject infinity when `False`. When `True`, temporarily handles infinity as missing during preprocessing and restores it for the model. | Prefer cleaning infinity upstream. Enable only when infinity has a deliberate meaning in your data. |
## Preprocessing on the GPU
`ENABLE_GPU_PREPROCESSING` moves supported quantile and squashing transforms, SVD feature generation, fingerprint creation, and feature shuffling to the model device. This can reduce preprocessing time on large datasets. Unsupported transforms still run on the CPU.
The base dataclass value is `False`, but a checkpoint can set a different value. Inspect the resolved configuration for your model. Try GPU preprocessing when you have more than about 10,000 rows and preprocessing is a visible part of runtime. It is less useful for small data.
## Settings to leave unchanged
The inference configuration also contains limits and compatibility controls used by the model and its checkpoint. They are not normal preprocessing tuning options:
* `MAX_NUMBER_OF_CLASSES`, `MAX_NUMBER_OF_FEATURES`, and `MAX_NUMBER_OF_SAMPLES` describe model limits.
* `MAX_CPU_SAMPLES` guards against very slow CPU inference.
* `FIX_NAN_BORDERS_AFTER_TARGET_TRANSFORM` repairs invalid regression distribution borders and should stay enabled.
* `USE_SKLEARN_16_DECIMAL_PRECISION` is a compatibility option, not a performance setting.
* Private keys beginning with `_` define task-specific internal defaults.
Use `ignore_pretraining_limits` through the estimator interface when appropriate. Do not increase the limit values inside `inference_config` to hide a warning.
## A practical tuning order
1. Fit and measure the unchanged model.
2. Check column types: declare categoricals, keep datetimes as datetime dtype, load free text as `string` dtype, and include group identifiers as categoricals.
3. For heavy imbalance or zero-inflated targets, try `"majority_downsample"` row subsampling and check the metric you care about.
4. For wide data beyond about 6,000 columns, raise `n_estimators` or tune the feature subsampling method.
5. For skewed regression targets, test one extra target transform.
6. For distribution shift, try `"quantile_uni_extrapolate"` alongside the default representation.
7. Try a limited number of polynomial features, then try `"all"` if the table is narrow.
8. Keep a change only when it improves validation results across several seeds or splits.
Preprocessing changes the data seen by every estimator. A useful transform on one dataset can remove signal on another, so validation is more important than choosing the most complex option.
This documentation is built and hosted on [Mintlify](https://mintlify.com), a developer documentation platform.